
Assay is an agent-operated software delivery pipeline with human governance. It organizes work into bounded requests, has separate agents implement, review and verify them, and leaves consequential decisions with people. Its current delivery boundary ends at verification on the main branch; deployment and customer outcomes need their own records.
AssayScore summarizes four aspects of a brief-based delivery system: how long work takes, where it waits, how often it passes without recorded repair, and how completed work compares with decision-queue delay. Its calculation is public, and its output includes the component scores, raw inputs and normalization baseline.
That transparency makes the number inspectable. It does not make it a complete productivity measure. Two of its current inputs are proxies, missing dimensions change the calculation, and its historical baseline belongs to the measured repository or reporting scope. A score of 80 is neither an industry percentile nor evidence that customers received 80 percent of the value they needed.
The useful reading starts with the score and continues into its parts. This article explains what each part currently means, how to reproduce the calculation and when a change in the headline should prompt investigation.
The unit of work and the reporting window
Assay organizes delivery around briefs: bounded requests carrying requirements and verification checks. Implementation, review, verification and final completion are separate events. That lets us ask how long a request took to finish, rather than treating every commit or merged PR as an equivalent unit of delivery.
AssayScore combines several views of that workflow. Speed uses authored briefs reaching done in the reporting window. Flow uses completed status-dwell intervals. Quality joins completed briefs to PR reviews and recorded evidence. Value combines size-weighted completions with closed decisions in the window.
These are related populations, but they are not one perfectly matched cohort. A decision closed this week can concern work completed in another week. A stage interval can finish this week while its brief remains unfinished. Keep those boundaries in mind when interpreting the composite.
statusgen is Assay's command-line tool for generating the work-status board and delivery reports from repository records. It computes AssayScore from work history and the linked records available to it. The current implementation is available in statusgen's AssayScore calculation. The formula below describes that implementation, including its present limitations.
The four components
| Component | Current input | Interpretation |
|---|---|---|
| Speed | Median authored-to-done lead time | Completion time relative to the scope's recent lead-time distribution |
| Flow | Selected completed workflow-state durations | A status-dwell proxy for touch time divided by touch plus wait time |
| Quality | First-pass yield among resolvable, readable completed-brief records | Recorded review and verification friction, with linked unresolved findings considered |
| Value | Size-weighted completed work divided by decision-queue dwell hours | Delivery relative to recorded decision delay; not measured business value or human labor |
Speed
Speed starts with lead time in days from a brief's authored date to its transition into done. The reporting window selects the completion event. Briefs whose authored date or effort cannot be resolved do not enter the sample.
The window's median is compared with the 10th and 90th percentiles of individual brief lead times in the trailing 90-day reference period. Lower lead time is better:
Speed = 100 × clamp((P90 − median lead time) / (P90 − P10), 0, 1)
Here clamp limits a value to the range zero to one. A median at the fast end of the band scores 100; one at the slow end scores zero. Values beyond either end remain at the corresponding boundary.
For an illustrative baseline with P10 of two days and P90 of ten days, a five-day median gives:
Speed = 100 × (10 − 5) / (10 − 2) = 62.5
This compares completed work with recent completed work. It leaves unfinished briefs out of the lead-time median, so queue age and unfinished work must remain visible beside it. A team can finish its short tasks faster while an old, difficult task continues to wait.
Work mix matters as well. A window dominated by small briefs can look faster than one dominated by large changes. The standalone lead-time report provides size breakdowns; the composite's Speed component is not itself a full adjustment for size or risk.
Flow
The intended concept is flow efficiency:
Flow = 100 × touch time / (touch time + wait time)
The current implementation derives both terms from the status historian. Completed in-progress intervals count as touch. Completed intervals in todo, implemented and verified count as wait. done and blocked intervals are excluded from this proxy.
An interval counts when a later transition closes it, with the closing instant determining window membership. The current open interval of an unfinished brief is not estimated. Fewer than five completed intervals, or no accumulated duration, makes the component unavailable.
If the included intervals contain 30 hours in progress and ten hours in the waiting states, Flow is 75. That means 75 percent of the counted state-dwell time was in progress. It does not establish 30 hours of active execution: in-progress work can pause, and verification can be active while the brief sits in a state classified as waiting.
Explicit active-work capture would improve that distinction. Until such evidence is integrated, calling this “actual working time” overstates the measurement.
Quality
Quality multiplies the first-pass-yield ratio by 100. The current calculation considers briefs reaching done that have a resolvable merged PR and readable review data. A counted brief passes when it has no recorded CHANGES_REQUESTED review, its last recognized verification verdict is not a failure, and no unresolved finding explicitly names it through the supported references.
Nine passing briefs out of ten counted briefs produce Quality 90. The counts matter as much as the percentage: nine out of ten provides much less evidence than 900 out of 1,000.
There are two important limits in the first-pass implementation. First, unlinked briefs and unreadable PR review records are excluded; a computable ratio can describe only a subset of the completed work. Second, its verification leg reads the last recognized verdict, not a complete immutable count of every historical verification failure. It therefore cannot establish that a brief never failed an earlier verification attempt.
Quality is also sensitive to review practice. A rigorous reviewer may request changes on defects that a weaker review would miss. First-pass yield can fall because detection improved. Conversely, a high yield can coexist with bugs discovered after release.
Read this component alongside substantiated findings, verification rework and escaped defects. The separate quality tools can trace fixing changes and examine process-stage attribution. Those results do not automatically become a defect-severity penalty in AssayScore.
Value
The numerator gives completed authored briefs effort weights of S = 1, M = 3 and L = 8. Issue-triage placeholders, which route reports before they become authored work, are excluded from this numerator. The weights are ordinal size points; they do not represent revenue, customer impact or dollars.
The denominator currently sums the creation-to-closure durations of decision-queue issues closed in the window. These are tracker records explicitly marked as awaiting a human decision:
Raw Value = completed effort points / decision-queue dwell hours
A decision open for a day contributes 24 hours even if the person resolving it spent only five minutes on it. Concurrent decisions accumulate separate durations. The ratio therefore measures throughput relative to decision delay, not output per active human hour. Review delay and time actively spent at approval gates are not included in this denominator.
Raw Value is normalized against its own historical band, with higher values better:
Value = 100 × clamp((Raw Value − P10) / (P90 − P10), 0, 1)
Its reference observations are seven-day throughput-to-decision-dwell ratios accumulated backwards over the trailing baseline horizon. Weeks with no positive decision hours cannot form a ratio and are skipped. The implementation uses whole seven-day buckets, so the oldest bucket can extend just beyond the nominal 90-day boundary.
For an illustrative raw value of 0.8 points per decision-dwell hour and a band from 0.1 to 1.1, Value is 70. A window with no decision hours produces an unavailable Value component, not infinite productivity or a perfect score.
The name “Value” is broader than the evidence currently supports. To determine business value, a project needs its own outcome observations, such as successful user tasks, reduced failure rates or lower operating burden among users exposed to the change.
How the components become one number
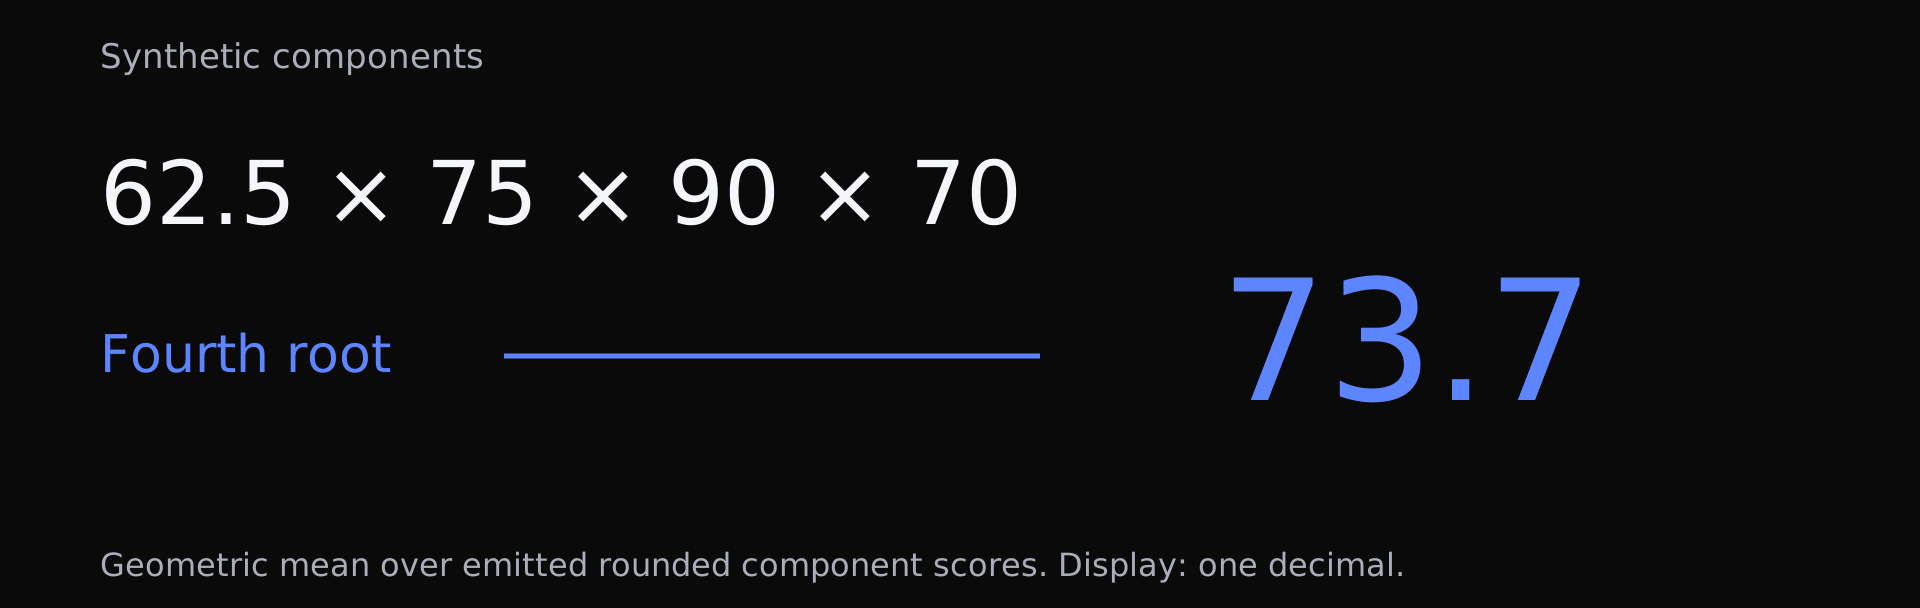
With all four components present, AssayScore is their equally weighted geometric mean:
AssayScore = (Speed × Flow × Quality × Value)^(1/4)
A worked example uses synthetic component values:
Speed   = 62.5
Flow    = 75
Quality = 90
Value   = 70

Product = 29,531,250
AssayScore = 29,531,250^(1/4) = 73.717476…
Displayed score = 73.7
The arithmetic mean would be 74.375. The geometric mean puts more pressure on imbalance. With scores of 100, 100, 100 and 1, the arithmetic mean is 75.25 while the geometric mean is about 31.6. Any measured zero component makes the product, and therefore the complete score, exactly zero.
This is a design choice about aggregation. It discourages compensating for a very weak dimension with strong ones, but it does not prevent gaming. Misclassifying effort, changing status timing, weakening reviews or hiding an unavailable component can still distort the result. Data integrity and review of the underlying behavior remain necessary.
The implementation rounds component scores and the reported composite to one decimal place. A reader reproducing the emitted value should use the reported components and the same rounding convention, rather than assume the output preserves unlimited precision.
Calculation conventions
For an exact reproduction, retain the events and implementation version as well as the exported summary. Reporting windows include their start and exclude their end: [since, until). The trailing baseline ends at until, so it can overlap the reporting window.
The implementation sorts a baseline of n values and selects zero-based index floor(n × q), capped at n − 1, for percentile fraction q. It rounds that value to one decimal. For example, the ten sorted lead times 1 through 10 days give P10 = 2 and P90 = 10 under this convention. A spreadsheet's interpolated percentile function may disagree. The median averages the two middle values for an even sample and rounds to one decimal.
Flow's ratio is rounded to three decimal places before conversion to its component score. Component scores are rounded to one decimal before the geometric mean, and the composite is rounded to one decimal. Use the emitted component scores to reproduce that composite.
Some exported raw inputs are display-rounded. Value normalization uses the unrounded underlying ratio, while its exported v_raw and decision_hours fields are rounded. Recomputing Value from those displayed fields alone can therefore differ at a rounding boundary; exact reproduction of that component requires the retained source events and baseline calculation.
Baselines and missing dimensions
Flow and Quality are already bounded ratios, so they do not need a normalization band. Speed and Value do. Each needs at least five usable baseline observations and a non-degenerate band: if P10 equals P90, normalization is unavailable.
The five-observation guard is not a statistical confidence guarantee, and it does not apply uniformly to all four components. Flow has its own five-interval guard. Quality can be computed from a smaller non-empty qualified sample. Sample size must remain visible even when the calculation is valid.
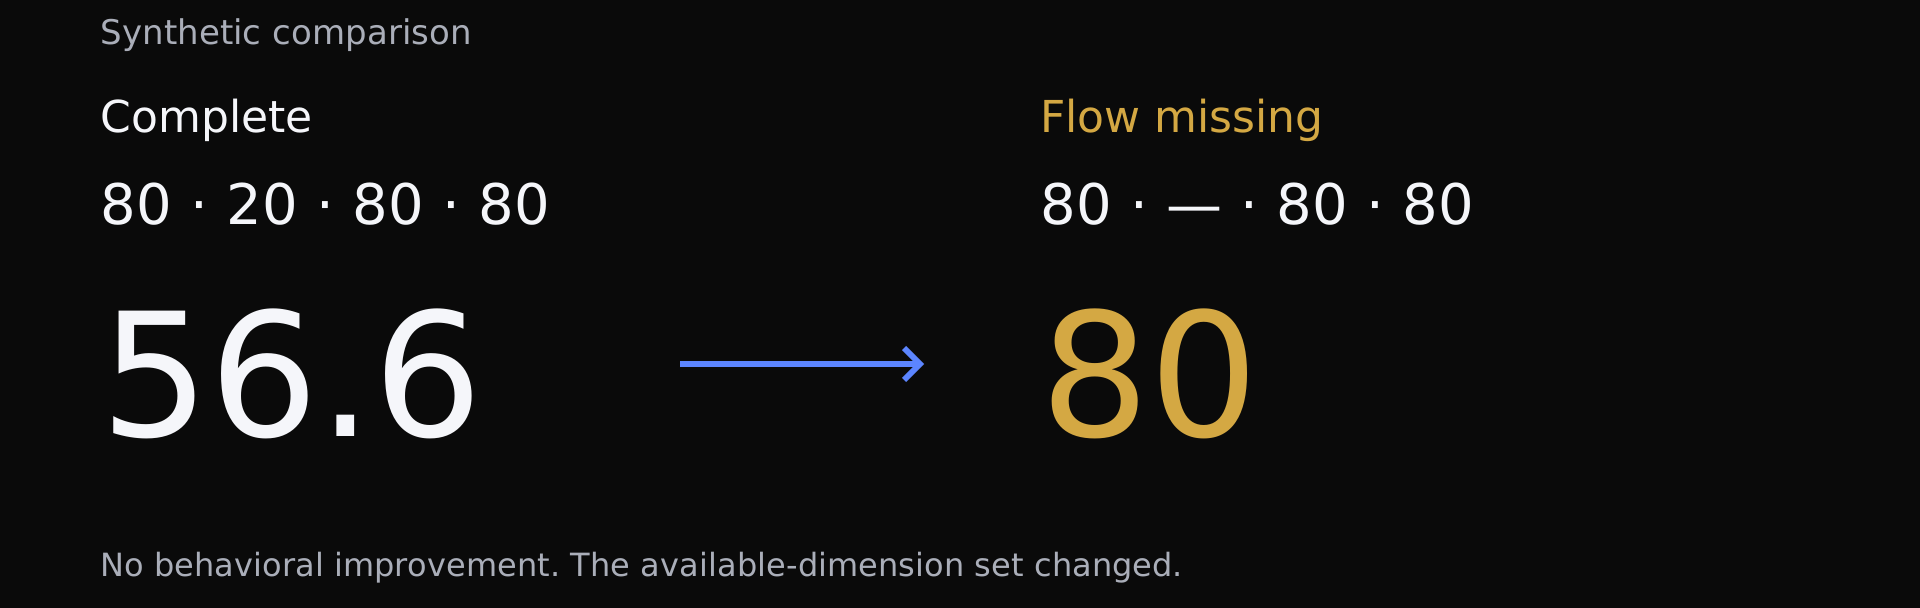
When a dimension is unavailable, the implementation excludes it from the product and changes the root to match the number of available dimensions:
Partial score = (product of available component scores)^(1 / available count)
If Flow is missing from the worked example:
(62.5 × 90 × 70)^(1/3) = 73.294860…
Displayed score = 73.3, incomplete, Flow missing
If every component is unavailable, the score is null with could-not-check. An unavailable input never becomes a measured zero.
A partial score can rise when a weak component disappears. Suppose Flow is 20 and all other components are 80. The full score is about 56.6. Lose Flow's data source and the remaining-component score becomes 80. Nothing improved in delivery; the calculation changed.
For that reason, compare headline values only after checking their available-dimension set, source coverage and population. A dashboard should show the incomplete state beside the number. It should never draw an uninterrupted improvement story across a missing-data boundary.
What should accompany every score
The JSON output includes the reporting window, generation time, component states and reasons, raw inputs, missing dimensions and the baseline window with its observation counts and bands. A consumer should preserve those fields even if its first view is compact.
It also needs to respect units. The standalone first-pass-yield output expresses a percentage; the AssayScore quality input expresses a ratio. A value of 1 can therefore mean 1 percent in the former and 100 percent in the latter. Guessing the unit from the size of the number is unsafe.
Raw inputs remain useful when the normalized headline is flat. If lead times steadily improve, the trailing baseline eventually moves with them. An identical Speed score months later can accompany a much shorter raw lead time. Conversely, a slow historical period can make today's performance look relatively strong. Preserve the raw trend and baseline together.
AssayScore is consequently unsuitable for cross-company league tables or individual performance rankings. Different scopes have different baselines, work mixes and evidence coverage. It also needs care around exploratory work, where a useful outcome may be resolving uncertainty or deciding to stop. Faster completion of a poorly chosen brief does not establish a better decision.
Using AssayScore on a project
Run the tool against an Assay-managed repository with the relevant history and forge access:
statusgen --root /path/to/project --assayscore --json
For a deliberate comparison, choose explicit time boundaries supported by your installed release and retain the result, tool version and repository revision. Keep the source exports or authorized evidence needed to investigate a surprising value. A later rerun can differ if issue classifications, findings or recorded verification evidence have changed.
Read the result in this order:
- Check the time window, freshness and available components.
- Inspect raw values, sample counts and normalization bands.
- Examine unfinished work and the workload mix.
- Compare review rigor, repair history and escaped defects.
- Choose a specific investigation or change, then evaluate its result with the relevant measure.
If Flow falls while Quality rises, the next question might concern added review work. If Speed rises while old work accumulates, completion selection may explain the improvement. If Value rises, inspect both completed points and decision dwell before concluding that people spent less time.
The action should follow the component evidence. “Increase AssayScore by ten points” does not identify which user or delivery problem needs solving.
How AssayScore fits the learning roadmap
AssayScore currently uses a fixed transparent formula. A separate command-line tool, qualgen, analyzes Git change patterns and potential defect origins. Its learned defect-risk library estimates risk for individual changes from historical features; that is a separate calculation. We do not need to make the composite opaque to introduce machine learning elsewhere in the system.
The planned feedback cycle uses richer evidence to nominate an investigation, compare an intervention with a baseline, independently assess quality and burden, and observe the result after adoption. A risk estimate might suggest deeper review of a change. An experiment might test a review method or identify a recurring gap in briefs. Neither conclusion follows from the composite score alone.
Future measurements can improve explicit active-time coverage, full-cohort cost and product-outcome assessment. Changing an input definition would require versioning the metric and preserving the earlier interpretation. A historical series should not silently switch from status dwell to measured active work, or from decision waiting to human labor.
For a team adopting AssayScore now, keep the raw component history and one record of the decision it informed. After the change, check whether the relevant waiting, rework or user outcome improved. That gives the score a concrete use while leaving room to revise the measure when better evidence becomes available.
The companion metrics and defect-attribution article explains how statusgen's delivery reports connect to qualgen, Assay's command-line analyzer of Git change patterns and potential defect origins. qualgen's learned-risk library evaluates individual changes; it does not compute AssayScore.
Disclaimer
This article describes the inspected November 2026 implementation. All numerical examples are synthetic. AssayScore summarizes selected delivery evidence; it does not measure individual performance, customer benefit or the probability that a change is defect-free. Compare like populations, available dimensions and calculation versions.
Case walkthrough: When a higher score hides less evidence
A higher delivery score can reflect less evidence. This walkthrough explains AssayScore through synthetic component values and a missing-data example: a complete score of 56.6 becomes a partial score of 80 without improved delivery behavior. Learn what the geometric mean summarizes and which inputs to inspect before comparing headline scores. AssayScore is a fixed delivery formula, separate from Pyx merge-risk assessment.
Explainer videoField guide: AssayScore: a guide to the calculation
A chaptered guide to AssayScore: Speed, Flow, Quality and Value; their input populations and limits; geometric-mean combination; missing dimensions; and changing historical baselines. Worked values are synthetic. The component names describe specific recorded proxies, not customer value, active labor or a guarantee of software quality. AssayScore is separate from Pyx merge-risk assessment.